
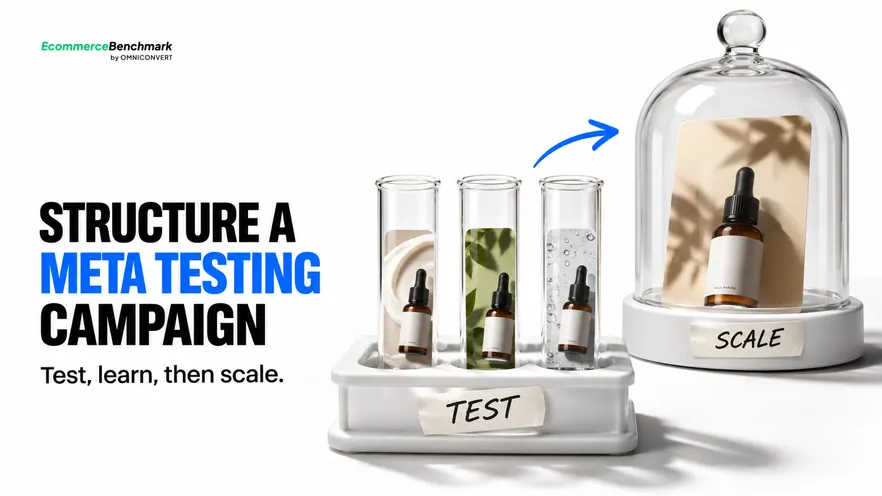
A discovery campaign is defined as a Meta campaign whose purpose is to produce information about which creative works rather than to buy conversions efficiently, which means it is judged on what it tells you and not on its return. To structure a Meta testing campaign properly you run that alongside a separate scaling campaign, ring-fence its budget, and write the exit rules before launch. Around 70% of carts are abandoned, so a winning ad can still be undone downstream [Baymard Institute, 2025]. This guide covers the split, the budget, the metrics and the graduation rule.
- Run discovery and scaling as two campaigns with two different jobs.
- Ring-fence the test budget and accept a lower return from it by design.
- Change one variable per ad set so a result points at something.
- Write the exit rule before launch: what spend, what metric, what call.
- Read upstream creative signals before return on ad spend at test budgets.
- Graduate a winner into the scaling campaign rather than raising its budget.
- Log every tested variable, because discovery only compounds if written down.
Omniconvert has measured creative and funnel performance across the CROBenchmark dataset of 7,000+ websites in 15+ industries, against 248+ audit criteria, over 13 years in eCommerce, covering 70,000+ experiments across 2,500+ Shopify stores [CROBenchmark Report 2026, Omniconvert]. The recurring fault in paid testing is not the creative. It is a structure that cannot produce a readable result.
Why you structure a Meta testing campaign as two campaigns
Put a new creative and an established one in the same ad set and watch what happens. Within two days most of the delivery is on the established one, which is correct behaviour from a system told to maximise results.
The consequence is that your test never happened. The new variant received a few hundred impressions, produced no statistically meaningful signal, and was switched off as a failure when it was never actually given a reading.
So the split is not a preference. It is the only structure in which a test can return information, because only a separate campaign lets you protect delivery to things that have not yet earned it.
Meta's own research tooling makes the discovery half easier than it used to be: the Meta Ad Library and the associated ad library research tools let you see which angles competitors have kept running, which is a cheap source of hypotheses before you spend anything [Meta, 2026].
What each campaign is for
Write the two jobs down before you build anything, because the structure follows from them and so does the reporting.
Discovery: several ad sets, one variable different in each, budget distributed deliberately rather than optimised, duration set by an exit rule. It will look inefficient. That is the price of the information.
Scaling: consolidated budget, proven creative only, delivery left alone to do what it is good at. Judged on cost per acquisition and on revenue, and changed as little as possible.
The consolidation question in the scaling half is its own argument, and it is covered in ABO vs CBO and in when to consolidate versus split your ad sets.
Ring-fence the test budget
This is a governance problem rather than a media problem. Everybody agrees testing matters when the quarter is going well, and the test campaign is the first line cut when it is not.
Set the share once, state plainly that its return will be lower by design, and report it separately so nobody blends it into the account average. A test campaign measured against the scaling campaign's efficiency will always look like waste.
The deeper reason to protect it is timing. Creative fatigue arrives whether or not you were ready, and a store with no tested alternatives has to scale something unproven at exactly the moment it cannot afford to experiment.
Meta's own advertiser guidance is explicit that an ad set re-enters a learning phase after significant edits, which is the mechanical reason the two budgets have to stay apart rather than be moved between each other mid-flight [Meta, 2026].
| Dimension | Discovery | Scaling |
|---|---|---|
| Purpose | Produce information | Produce revenue |
| Budget logic | Distributed deliberately | Consolidated, optimised |
| Variables | One per ad set | None, held stable |
| Judged on | Learning rate | Cost per acquisition |
| Expected return | Lower, by design | The account average |
| Edit frequency | Ends at the exit rule | As rarely as possible |
The way paid teams most often lose a year of learning is by running the test campaign without a written exit rule and then settling every test in a meeting. A variant is up on day three, somebody wants to scale it. It is down on day five, somebody wants to kill it. Both calls get made on spend levels where the numbers cannot support either, and because the decision is social rather than mechanical it is won by whoever is most confident in the room. Six months later the account has run forty tests and the team cannot name five things it learned, because no test ever ran to a threshold anybody agreed on beforehand. The tell is a creative brief that still begins from opinion after a year of testing.
Read the metrics the creative controls
A creative decides whether somebody stops, keeps watching and clicks. It does not decide whether your product page answers a sizing question or whether delivery cost appears late, and holding it responsible for those produces random results.
So read the upstream signals first: retention past the opening seconds, click-through to the product page, cost per landing page view. Those reach a stable reading quickly and point at the creative itself.
Then confirm with conversion once the winner has earned enough spend for that number to mean something. Two gates rather than one, which is slower to describe and much faster in practice than restarting an unreadable test.
Around 70% of carts are abandoned on average, with extra costs and missing information the most cited reasons [Baymard Institute, 2025], and Baymard Institute has found the same pattern for years. A creative test judged on purchases is partly measuring your checkout.
The anatomy of what you are varying is in hook, angle, CTA.
The Graduation Rule
This is the step most often done backwards, and it is expensive because it destroys the thing you just bought. You spent money establishing stable delivery on a variant, then edited the ad set and sent it back to the start.
Graduate instead. Build the winner into the scaling campaign as a new ad, leave the discovery ad set alone or switch it off, and let the scaling campaign absorb it alongside the other proven creative.
Then free the discovery slot for the next hypothesis. The point of a discovery campaign is throughput of questions, and a slot occupied by a known answer is a slot producing nothing.
Nextbase ran one Omniconvert A/B test on desktop of a product category organised by use case and recorded a +26.16% conversion rate, +23.7% revenue per user, and a 98.53% chance to win. [Omniconvert, Nextbase case study] That is an on-site testing result rather than a paid media result, and the transferable discipline is the one this whole structure exists to protect: one variable, a pre-agreed threshold, and no reading of the first few days.
What a performance lead should do this week
- Write the exit rule. Spend threshold, deciding metric, the call.
- Split the campaigns. Discovery and scaling, separate budgets.
- Reduce to one variable. Per ad set, even where it feels slow.
- Start the creative log. Variable tested, result, date.
Before any of it, see where your store sits across the six benchmark dimensions, including Creative and Ads, with a free leaderboard score, and take the paid audit report where you want the detail behind it. Once you know where you rank, Omniconvert Commander (formerly Nexus) is an AI for eCommerce growth engine that unifies commerce data, prioritises experiments by True Profit, and generates campaigns and creative you approve before they go live. The budget-split half of this argument is in the budget-testing framework, and the on-site method is the CRO audit checklist.
Frequently asked questions
How should you structure a Meta testing campaign?
As two campaigns rather than one. A discovery campaign exists to find out which creative and which angle work, and a scaling campaign exists to spend efficiently on what is already known. Put both jobs in one campaign and delivery optimisation will quietly defund the untested creative before it produces a usable reading.
Why does one combined campaign fail?
Because the system is doing exactly what you asked. Told to maximise results, it moves delivery toward the ad with the established record, which is the proven one. The new creative never accumulates enough events to be judged, so the campaign performs adequately and teaches you nothing.
How much budget should discovery get?
A fixed share you are willing to spend on information, decided in advance and not revisited weekly. The exact figure matters less than the fact that it is ring-fenced, because an unprotected test budget is the first thing cut when a week looks weak, which is also the week you most need to know what works.
What metric decides a test?
Not return on ad spend, at least not first. At test-level budgets that figure is mostly noise. Read the upstream signals the creative actually controls, such as the share of viewers who stay past the opening seconds and cost per click through to the product page, then confirm with conversion once spend justifies it.
What is the graduation rule?
A winner is relaunched in the scaling campaign rather than promoted in place. Raising the budget of the ad set that proved it is a significant edit, which returns that ad set to the learning phase and throws away the stable delivery you just paid to establish.
How many variables can one test carry?
One per ad set. Change the hook and the format together and a result tells you that something worked without telling you what. Teams tolerate this because it feels faster, and it is faster at producing outcomes you cannot reuse on the next creative.
Write the exit rule first
Before you rebuild anything in the ads manager, write one paragraph: at what spend a test is decided, which metric decides it, and who makes the call. That paragraph is worth more than the structure, because a clean two-campaign setup still produces nothing if every test is settled by whoever is most certain in the room on day three.
Then split the campaigns, ring-fence the discovery budget, and reduce each ad set to one variable. Keep a plain log of what you tested and what came back. A year of that is a creative strategy built from evidence, which is a different asset from a year of tests nobody can summarise.