
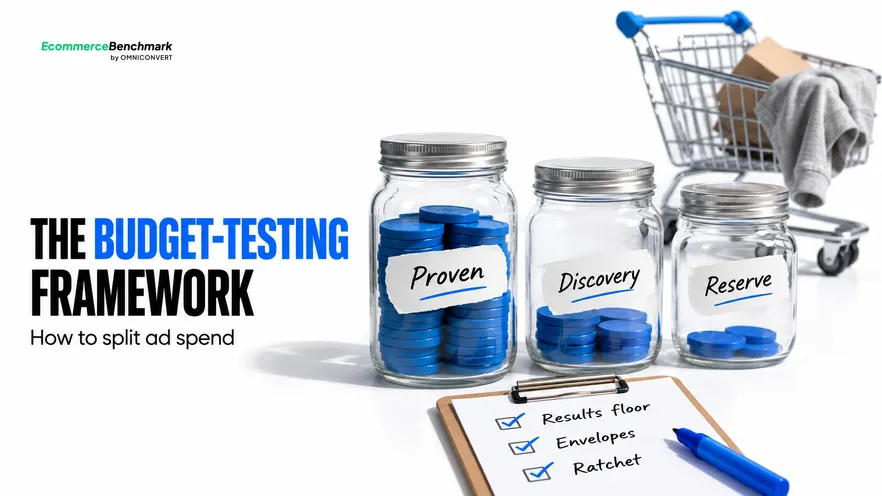
A results floor is defined as the minimum number of conversion events a variant must produce before its performance is read at all, which replaces a day count as the thing that ends a test. The budget-testing framework pairs that floor with three spend envelopes, proven, discovery and an unspent reserve, so a test never competes with the business and a winner is never settled on three days of noise. Around 70% of carts are abandoned, so creative is only ever part of the result [Baymard Institute, 2025]. This guide covers the envelopes, the floor and the ratchet.
- Split spend into three envelopes: proven, discovery and an unspent reserve.
- End tests on a results floor, never on a number of days elapsed.
- Remove live tests from the daily report so nobody reads them early.
- Scale a winner in fixed steps, letting delivery settle between them.
- Keep the reserve unspent so scaling never defunds what already works.
- Treat the two errors as unequal: a dead winner costs far more than a slow loser.
Omniconvert has measured experiment discipline across the CROBenchmark dataset of 7,000+ websites in 15+ industries, against 248+ audit criteria, over 13 years in eCommerce, covering 70,000+ experiments across 2,500+ Shopify stores [CROBenchmark Report 2026, Omniconvert]. The most common failure in paid testing is not a bad hypothesis. It is a good variant stopped before it could be read.
What the budget-testing framework solves
Most paid accounts do not have a testing problem in the sense of lacking ideas. They have a problem in which every test is implicitly an argument about budget, and every test is judged before it has produced enough evidence to judge.
Both are structural, which is good news, because structural problems are fixed once rather than negotiated weekly. Decide the envelopes and the floor, write them down, and the decisions stop being social.
The campaign architecture that these envelopes fund is a separate argument, covered in structure a Meta testing campaign. This article is about the money and about when to stop looking.
Three envelopes
The first two are familiar even where they are not formalised. The third is the one almost nobody holds, and its absence is why winners get scaled slowly.
Think about what happens without a reserve. A variant wins, and promoting it means cutting the proven campaign, which means somebody has to accept a short-term efficiency loss for a long-term gain. That argument is hard to win in a monthly review, so the winner gets a small increase and the test's value is never realised.
With a reserve, scaling is a release rather than a trade. The money was already allocated to this, the decision was made before anyone knew which variant would win, and there is nobody to argue with.
The ratios matter less than the separation. Set them to whatever your margin tolerates, state that the discovery envelope will return less by design, and report the three separately so nobody blends a deliberate information cost into the account's efficiency.
Meta's own ad library research tools and the public Meta Ad Library make the discovery envelope stretch further, because an angle a competitor has kept live for months is a cheaper hypothesis than one invented in a workshop [Meta, 2026].
The results floor replaces the day count
This is the part that saves winners. A variant with six conversions has a plausible performance range so wide that it covers both your best ad and your worst, and nothing about waiting three days narrows it if those three days produced six conversions.
So state the floor in results. Until a variant reaches it, its numbers are not read, not reported and not discussed. After it, they are read once and a decision is made.
Two things follow. Tests on low-volume products take longer, which is honest rather than inconvenient. And the number of simultaneous tests you can run is capped by your conversion volume, which is the real constraint most accounts ignore by running more variants than their traffic can resolve.
The launch period makes an early reading worse still. Meta's advertiser guidance describes a learning phase in which delivery is unstable until an ad set has accumulated enough events, so the first days of a test are both the least informative and the most tempting to read [Meta, 2026].
| Early signal | What it indicates | What to do |
|---|---|---|
| High cost per result, day two | Unstable launch delivery | Wait for the floor |
| Zero results, day one | Small sample, nothing more | Do not report it |
| Worse than the proven ad | Comparison against a mature ad | Compare at equal maturity |
| Weak weekend numbers | Weekday effect | Span a full week |
| Return on ad spend swinging | Too few orders to divide | Read upstream metrics |
| Good clicks, no purchases | Possibly a landing-page fault | Check the page, not the ad |
The way paid teams most reliably destroy their own testing is by putting live tests in the daily performance report. Nobody decides to kill winners early. What happens is that a variant appears in a shared dashboard on day two at triple the target cost per acquisition, somebody senior sees it next to the proven campaign, and the question arrives as why are we still spending on that. Defending it requires explaining sampling variance in a channel where everyone is confident they can read a number, so the variant gets paused to end the conversation. The fix is mechanical: remove in-flight tests from that report until they reach the floor. The tell is an account where every test that ever got scaled happened to perform well in its first forty-eight hours.
Scale with a ratchet
Having protected a winner through its test, the next common way to lose it is to scale it too fast. A large budget change is a significant edit, delivery destabilises, performance drops, and the ad is written off as something that did not survive scale.
Frequently it would have. What failed was the method of raising it. Fixed increments with a settling period between them keep the ad in the state you measured.
The reserve envelope is what makes the ratchet possible. Each step up is funded from money held for exactly this, so the steps are paced by delivery stability rather than by how long it takes to win a budget argument.
Around 70% of carts are abandoned on average, with extra costs and missing information the most cited reasons [Baymard Institute, 2025], and Baymard Institute has measured the same pattern for years. If a winning ad stops working at scale, check the page it sends people to before blaming the creative.
The structural half of the scaling question, consolidated against split budgets, is in ABO vs CBO.
The two errors are not equal
Teams act as though stopping early and stopping late carry similar costs, and they do not. One is a small bounded expense and the other is an unbounded opportunity loss that never appears in any report, because nothing records the revenue from an ad you turned off.
Which is why the bias should be deliberately slow. Not indefinite, because a floor is a limit in both directions, but slow enough that no variant is ever judged before its evidence exists.
In one desktop A/B test, a redesigned add-to-cart pop-up tested with Omniconvert gave LEROY MERLIN Romania a +16.8% conversion rate, +24.19% revenue per user, and a 99.66% chance to win. [Omniconvert, LEROY MERLIN Romania case study] That is an on-site testing result rather than a paid media result, and the chance-to-win figure is the point: the test only counted when results were read at a threshold rather than when somebody first looked.
What you are varying inside each test is covered in hook, angle, CTA.
What a performance lead should do this week
- Write the three envelopes. With the reserve held unspent.
- Set the results floor. In events, not in days.
- Remove live tests from the daily report. Until they hit the floor.
- Define the ratchet steps. Increment size and settling period.
Before any of it, see where your store sits across the six benchmark dimensions, Creative and Ads included, with a free leaderboard score, and take the paid audit report where you want the detail behind the score. Once you know where you rank, Omniconvert Commander (formerly Nexus) is an AI for eCommerce growth engine that unifies commerce data, prioritises experiments by True Profit, and generates campaigns and creative you approve before they go live. The on-site method is the CRO audit checklist.
Frequently asked questions
What is the budget-testing framework?
A way of splitting paid budget into three envelopes, proven spend, discovery spend and an unspent reserve, and ending tests on a results floor rather than on a number of days. The envelopes stop a test from competing with the business, and the floor stops a winner from being judged before it has produced enough events to judge.
Why do winning ads get killed early?
Because an early reading is close to random. With a handful of conversions the range of plausible performance is enormous, so a genuinely good variant will often look poor for its first days. Add an unstable delivery period at launch and a bad weekday, and a test stopped on day three is being settled by noise.
What is a results floor?
The number of conversion events a variant must produce before anybody reads its numbers. It replaces the day count because days are not what variance depends on. Twenty results in four days and twenty results in eleven days carry the same weight, and three days carrying two results carry none.
Why hold a reserve envelope?
So that scaling a winner never means defunding something that works. Without a reserve, every promotion is a trade against the proven campaign, which makes the decision political and slow. A held-back reserve turns scaling into a budget release rather than an argument.
How fast should a winner be scaled?
In steps, with a pause between them. A large budget increase is a significant edit, so it returns the ad set to an unstable delivery period and the performance you measured no longer applies. Raising in fixed increments and letting each one settle keeps the result you paid to establish.
Is it not expensive to let losers run longer?
It is cheap and it is bounded. A losing variant left running to its floor costs a few extra days of a small test budget. A winner killed on day three costs every month of return it would have produced. The two mistakes are not symmetrical, which is why the default should be patience.
Take live tests out of the daily report
Of everything here, the change that protects the most money is the cheapest: stop showing in-flight variants in the report senior people read every morning. A test on day two at triple the target cost invites a decision nobody should be making, and defending it costs more political capital than the test is worth. Hold them back until they reach the floor.
Then write the three envelopes down, with the reserve genuinely unspent, and state the floor in results rather than in days. None of this needs a tool or a migration. It needs a page of agreed rules, and it changes testing from an activity that generates opinions into one that generates knowledge you can spend against.